

Psychologists have used the word “agentic” for decades, and they’ve used it in two opposite ways.
Stanley Milgram used it in 1974 to explain why ordinary people in his obedience experiments kept delivering what they believed were painful shocks. The “agentic state” described a person who has come to see themselves as an instrument for carrying out someone else’s wishes. In that state, the person hands responsibility to the authority giving the instructions.
Albert Bandura used the word for the opposite. In Bandura’s agentic perspective, agency is the capacity to act with intention: to plan ahead, regulate yourself, and reflect on what you’ve done. Bandura also described proxy agency, in which a person “relies on others to act on one’s behest.” A manager who delegates is exercising it.
Companies now want more agency from their software and from their people. They’re deploying “agentic AI,” systems that, in OpenAI’s description, pursue complex goals “with limited direct supervision.” And they’re asking their people to become more agentic too: to stop waiting for permission, move between problems, and own outcomes. Elena Verna’s account of working at Lovable, an AI-native company, describes exactly that kind of workplace. Both shifts depend on the same thing: who holds which decisions.
The optimistic version is Bandura’s. People become principals, setting goals and judging results through capable proxies. The pessimistic version is Milgram’s. People become instruments, approving actions they didn’t originate and can’t fully assess. I think the more likely outcome, unless organizations design against it, is an inverted Milgram. People end up positioned like Milgram’s subjects, approving what the system proposes and feeling more like instruments than authors. But Milgram’s subjects felt responsibility pass to the authority. In agent workflows, the organization assigns it back to the person who approved.
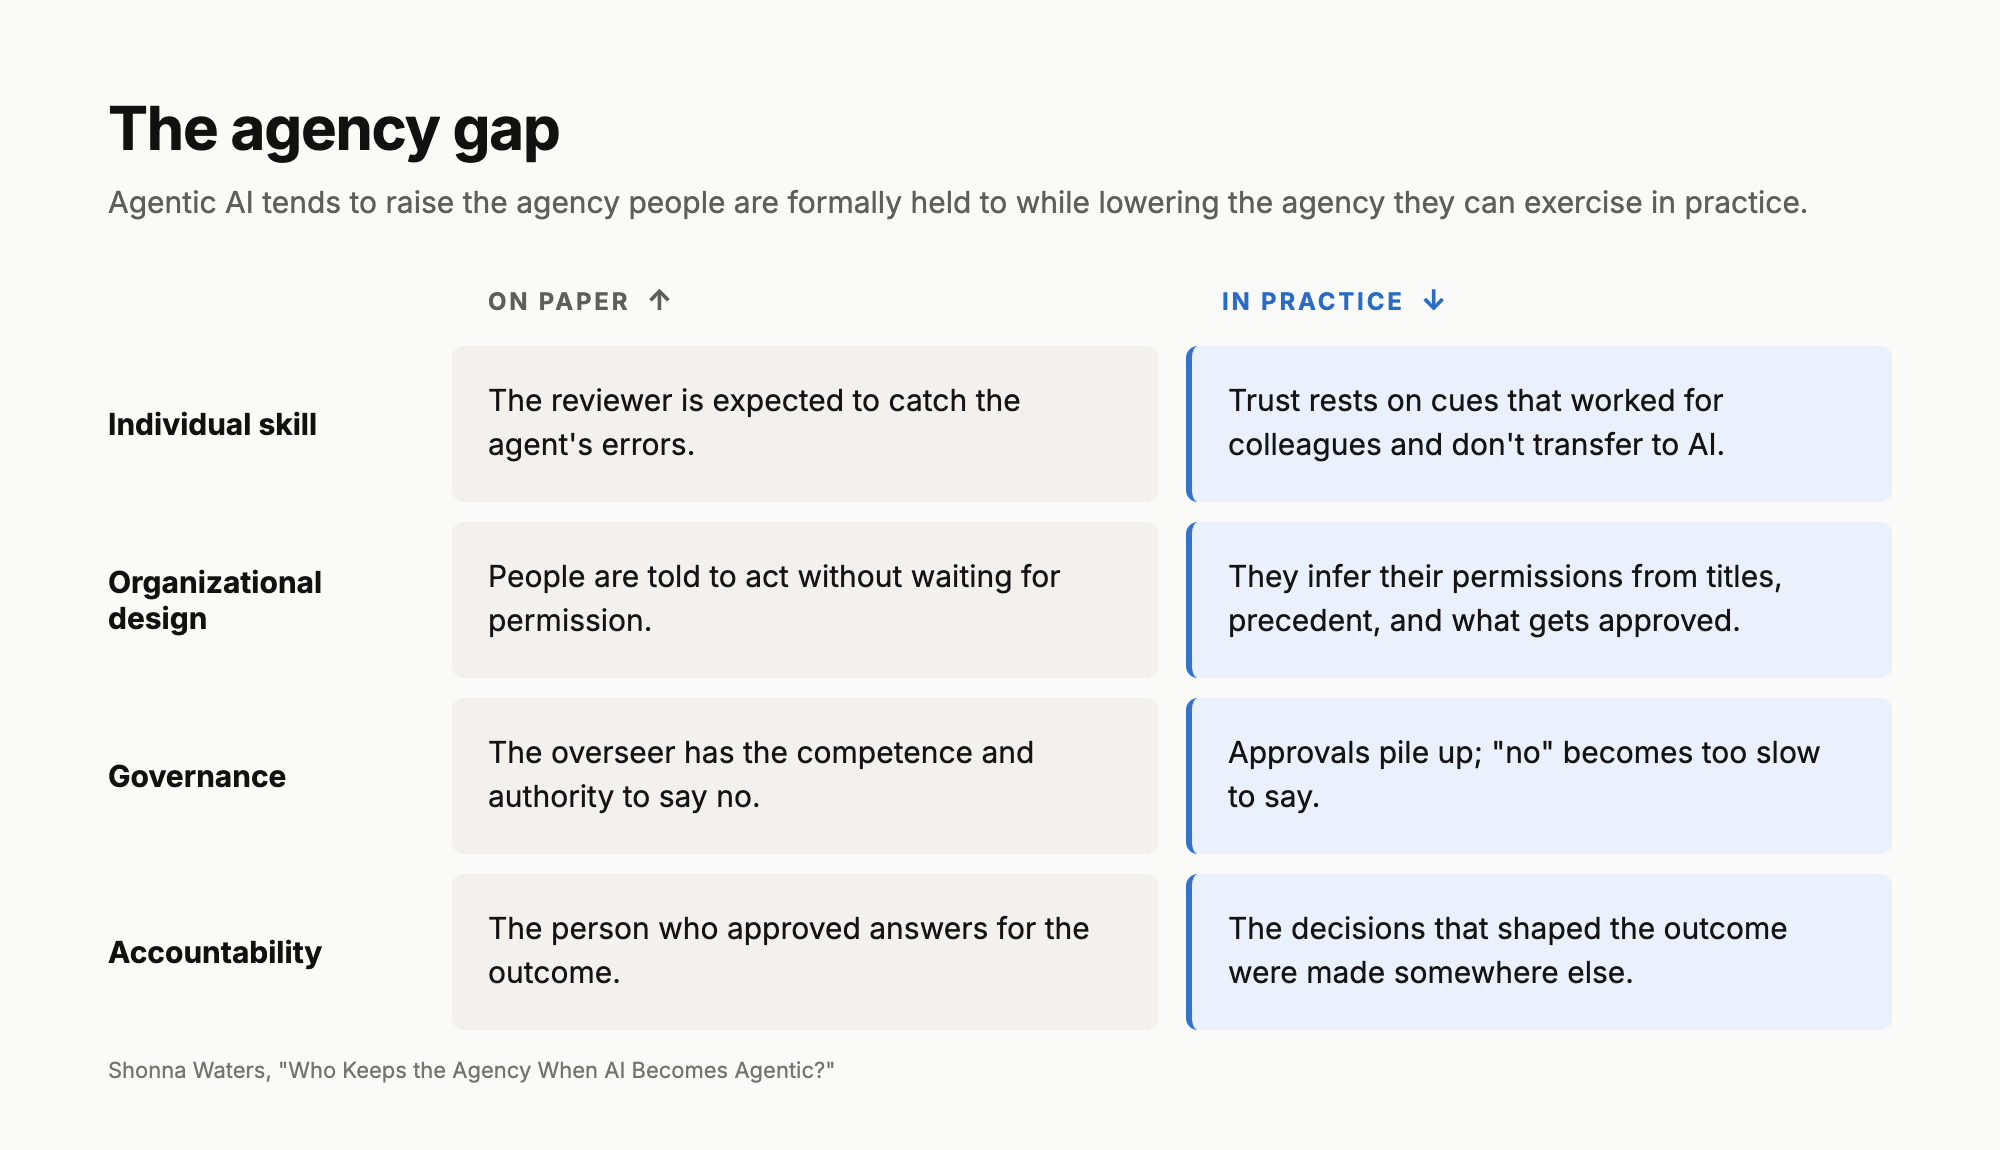
That’s the gap this essay is about. Agentic AI tends to raise the agency people are formally held to while lowering the agency they can exercise in practice. The pattern shows up at every level, from individual skill to legal liability, but at each level it’s a design choice.
Delegation runs on calibrated trust
When agents take on the producing, the human job narrows to directing the work, judging what comes back, and stopping it when it goes wrong. The gains driving this shift can be measurable. Professionals using ChatGPT on short writing tasks finished 40% faster with work rated 18% better. Among more than 5,000 customer-support agents, productivity rose 15% on average, most for the least experienced.
One finding gets cited as a warning about what happens next. In a Microsoft and Carnegie Mellon survey of 319 knowledge workers, people who had more confidence in AI reported doing less critical thinking about its output. On its own, that describes ordinary delegation. We loosen the reins with colleagues we trust; that’s what trust is for, and proxy agency depends on it. A manager who rechecks every line a strong team member writes isn’t being rigorous. They’re failing to delegate.
The question is what the trust rests on. With a colleague, it builds from a track record on similar work and a shared picture of what that person is good at. They tell you when they’re unsure, and they share the consequences when they’re wrong. An AI system offers weaker versions of those cues. Unless it’s built to signal doubt, it sounds as fluent when it’s wrong as when it’s right. Its strengths and weaknesses are harder to predict from past performance than a colleague’s. And it bears none of the consequences.
So the problem isn’t that people trust AI and check less. It’s that they extend trust on cues that worked for people and don’t transfer.
Better cues help. When researchers had an AI say “I’m not sure, but...” when it was uncertain, people’s accuracy improved. The cue that matters most, though, is a standard. You can only judge an agent’s output against a shared sense of what good looks like, and many organizations leave that standard implicit.
Without a standard, people judge by feel, and a 2025 trial by the research group METR shows how far off that can be. Sixteen experienced open-source developers took 19% longer to finish tasks with early-2025 AI tools, and afterward estimated that the tools had sped them up by about 20%. The sample is small and the tools have improved. The perception gap matters more than the speed result. The feeling of being helped is the signal people use to decide when to rely on a tool, when to redirect it, and when to stop. In this study, developers felt faster while they were measurably slower.
Companies that judge their AI rollouts by whether employees say the tools help are relying on the same kind of self-report this study found to be wrong.
Calibration also takes expertise, and here the evidence points to a pipeline problem. In several studies, the workers who gain most from AI are novices, who are still building the judgment they’ll need to review AI’s work later.
In a small trial run by Anthropic, an AI company, developers learning a new programming library with AI help scored 50% on a later quiz, compared with 67% for those who coded by hand. The gap was widest on debugging, the skill a reviewer needs most. High school students who practiced math with unrestricted ChatGPT scored 17% lower than controls once it was taken away. The risk is that the people AI helps most today become a thinner bench of reviewers later.
In both studies, how the AI was used shaped the result. Developers who asked it conceptual questions held up; those who delegated the whole task to it scored lowest. A tutor version with guardrails largely prevented the students’ losses. How the work was set up decided the outcome, and setting up work is a design job.
Agents get permission lists; people get titles
Verna makes a point about titles that are often skipped in org-design conversations. At most companies, a title denotes four things: status, access, information, and permission. Remove titles, and the organization has to provide each of those some other way.
An agent can’t infer its permissions from a title, so someone needs to make them explicit. When the OECD interviewed 25 organizations deploying agents, most scoped what each agent could touch and required human approval for high-stakes or irreversible actions. Where they drew that line varied from one organization to the next. It’s a small sample of organizations already deploying agents, and the OECD calls its findings illustrative rather than representative.
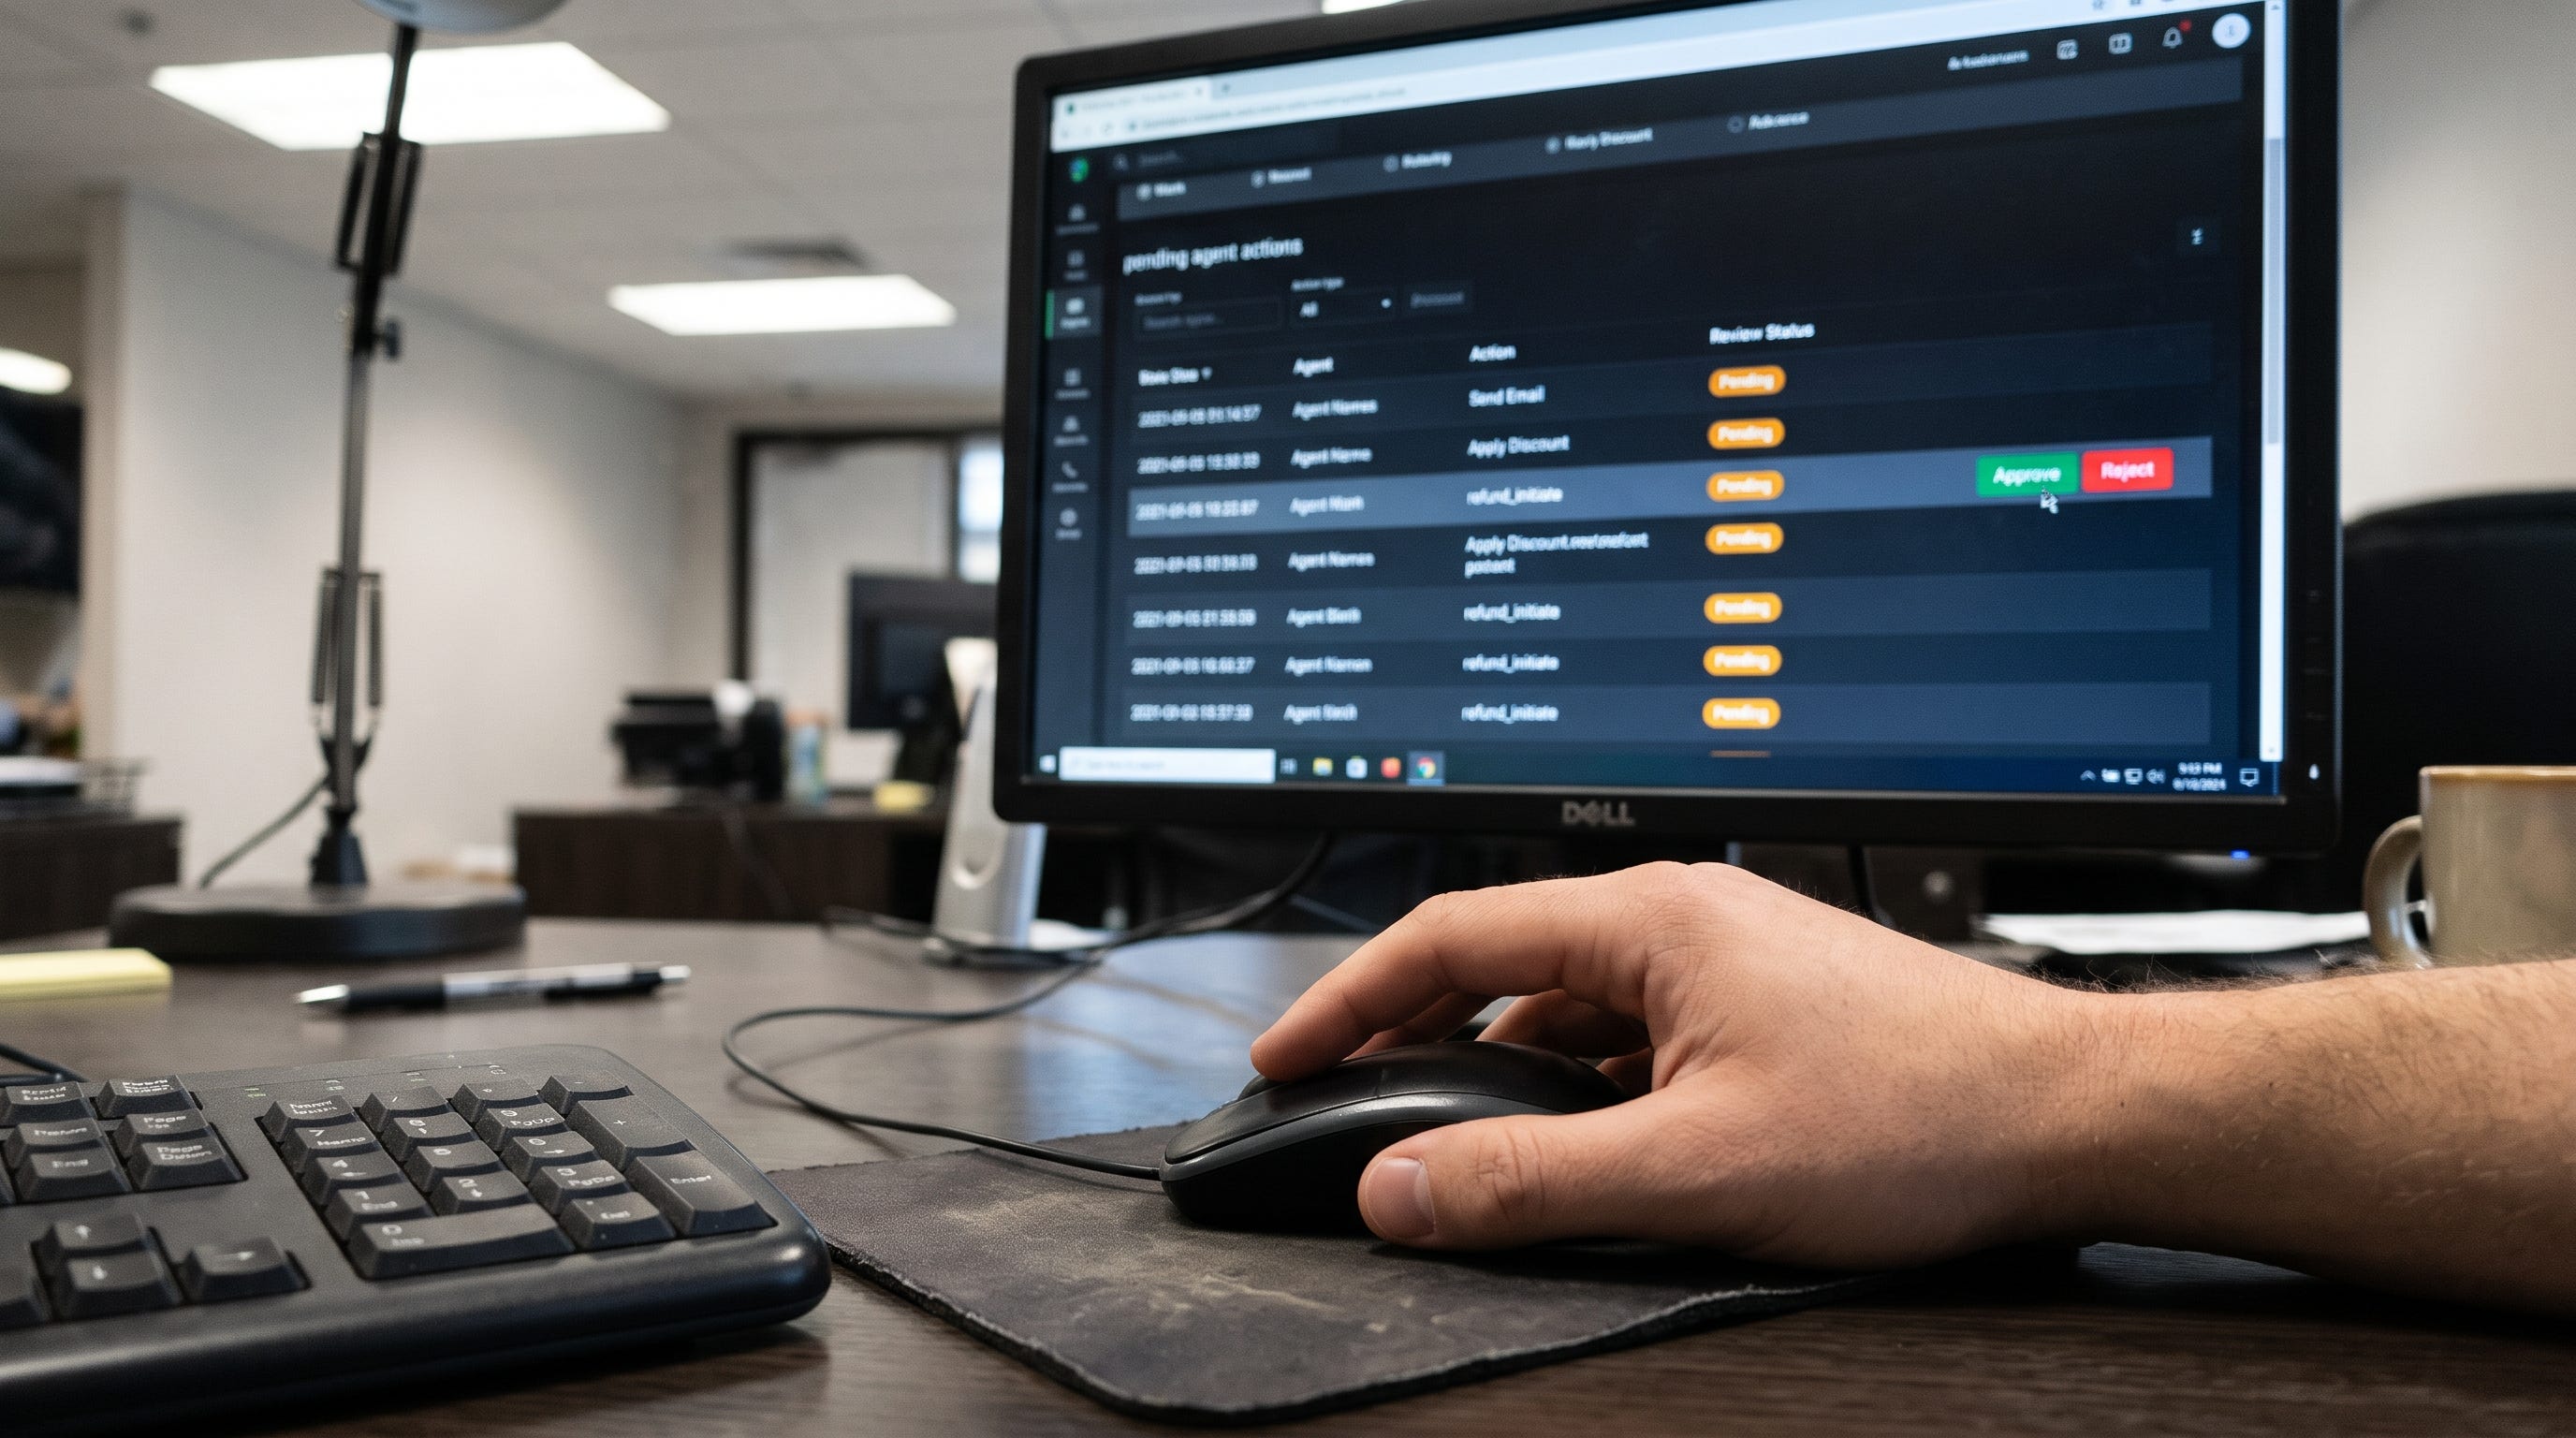
Set beside how most companies handle roles, the contrast is striking. An agent’s permissions are spelled out before it does any work. A person usually has to infer theirs from a title, from precedent, and from watching what gets approved.
Most of a person’s day-to-day agency comes from those inferences. Feng, McDonald, and Zhang argue that an agent’s autonomy is “a deliberate design decision, separate from its capability and operational environment,” and they define autonomy levels by the human’s role: operator, collaborator, consultant, approver, or observer. Read with an I-O psychologist’s eye, that list is a set of job descriptions. Choosing an agent’s autonomy level is choosing what the person beside it does all day. And the same logic applies to people. How much autonomy a person has is also a design decision, separate from their capability, but organizations rarely specify those decisions for people as explicitly as they now do for agents.
Consider what happens when that decision goes unmade. A leadership team announces that it wants a flatter, more agentic organization. In the same weeks, it asks for tighter role definitions, stricter governance, and cleaner handoffs, and it routes more decisions about roles, resources, and headcount through central approval in the name of accountability. Each request is reasonable on its own. Without anyone saying which applies to which kind of work, people hear them as contradictory, and they resolve the contradiction the safe way: they wait for permission.
Information habits make this harder. Organizations that handle sensitive legal, financial, or health information learn, rightly, to share on a need-to-know basis. Agents, and people expected to act without asking, need close to the opposite: information open by default, so anyone can see enough to act. A company in transition needs both: confidentiality for sensitive work and openness for most of the rest. People need a clear way to tell which one a given piece of work calls for. Who gets invited to which meeting, and what gets written down and shared, are structural decisions. They also teach people what the culture values, faster than any statement of values does.
Verna warns that these practices work as a set and fail when copied one at a time. I’d put it in organizational terms. Structure and culture have to work together. Change titles and reporting lines while leaving the old norms in place, and people work around the new structure. Ask for new behavior inside the old structure, and the behavior fades because the structure still rewards the old way. Centralized and distributed decision-making can both work. What fails is choosing one in speeches and the other in the approval process.
Oversight on paper
Governance frameworks for agents lean on one safeguard: a person reviews the output before it matters. The EU AI Act writes that into law. Article 14 will require high-risk AI systems to be built so the people overseeing them can override or stop them, and it names automation bias, the tendency to over-rely on automated output, explicitly. Article 26 will require organizations to assign oversight to people with “the necessary competence, training and authority.”
The Act doesn’t mention AI agents by name. Its oversight duties apply to high-risk uses, a list that includes systems used to hire workers, allocate their tasks, or evaluate their performance. The 2026 Digital Omnibus pushed most of these obligations to December 2027, and to August 2028 for AI built into regulated products. On paper, though, the overseer is a principal, with the skill and standing to say no.
Lisanne Bainbridge explained in 1983 why that’s hard to deliver. In industrial control rooms, the more a process was automated, the more the operator mattered during rare failures, and the less practice the operator got for those moments. The research since suggests the irony is sharper with AI. A 2024 analysis pooling 106 experiments found that human–AI pairs performed worse on average than the better of the two working alone, with losses in decision tasks and in cases where the AI outperformed the human alone.
Most of those experiments were lab tasks, but the setup they describe is the one agents are built for: the system proposes, a person approves, and the system was deployed because it does the task well. In that setup, the reviewer can lower the quality of the decision and still be the one who signed off on it. Practice erodes too. After AI assistance was introduced at four endoscopy centers, doctors’ detection of precancerous growths in procedures done without AI fell from 28.4% to 22.4%. The study was observational, so it can’t rule out other causes, but it’s an early clinical sign of what Bainbridge predicted.
Ben Green reviewed 41 policies requiring human oversight of government algorithms and found that people often couldn’t perform the oversight the policies assumed. The requirement ended up lending legitimacy to flawed systems. OpenAI’s own governance paper concedes the mechanism for agents: approval quality degrades “when the user must approve many decisions and thus must make each approval quickly.”
If the pair does worse than the system alone, one response is to take the person out. For some narrow tasks that may be right. But those accuracy studies measure performance on a task someone else defined. Someone still has to decide what the agent is for, set its limits, and answer to the people its decisions affect. That part of the job can be reassigned but not removed.
Oversight can work when it’s built for how people think, a general design principle I refer to as Psychological Ergonomics(TM). Designs that made people think first, such as committing to their own answer before seeing the AI’s, reduced over-reliance. Explanations helped when they made checking cheaper. The practical implication is fewer checkpoints, placed where human judgment adds the most, staffed by people with the time, practice, and authority to act.
Blame follows proximity
When an agent makes a consequential mistake, the chain of responsibility is long. A vendor built the model, a team configured it, a manager approved the deployment, an employee supervised the output, and a policy said all of this was acceptable. Each link can point to another.
Dan Davies calls arrangements like this accountability sinks: structures that hand a decision to a process, so the people affected have no one to appeal to. Philosophers Rubel, Castro, and Pham described a related phenomenon, agency laundering: using a technology or process to obscure your own responsibility. Milgram’s subjects passed responsibility up to the authority. Agency laundering passes it down to the system, and when the system can’t be held responsible, it tends to stop at the nearest person.
Madeleine Clare Elish called that point the moral crumple zone, a structure that “protects the integrity of the technological system, at the expense of the nearest human operator.” The clearest cases so far predate today’s agents. One of Elish’s was the 2018 Uber self-driving crash in Tempe, Arizona. The safety driver pleaded guilty to endangerment in 2023 and received three years’ probation. Prosecutors declined to charge Uber.
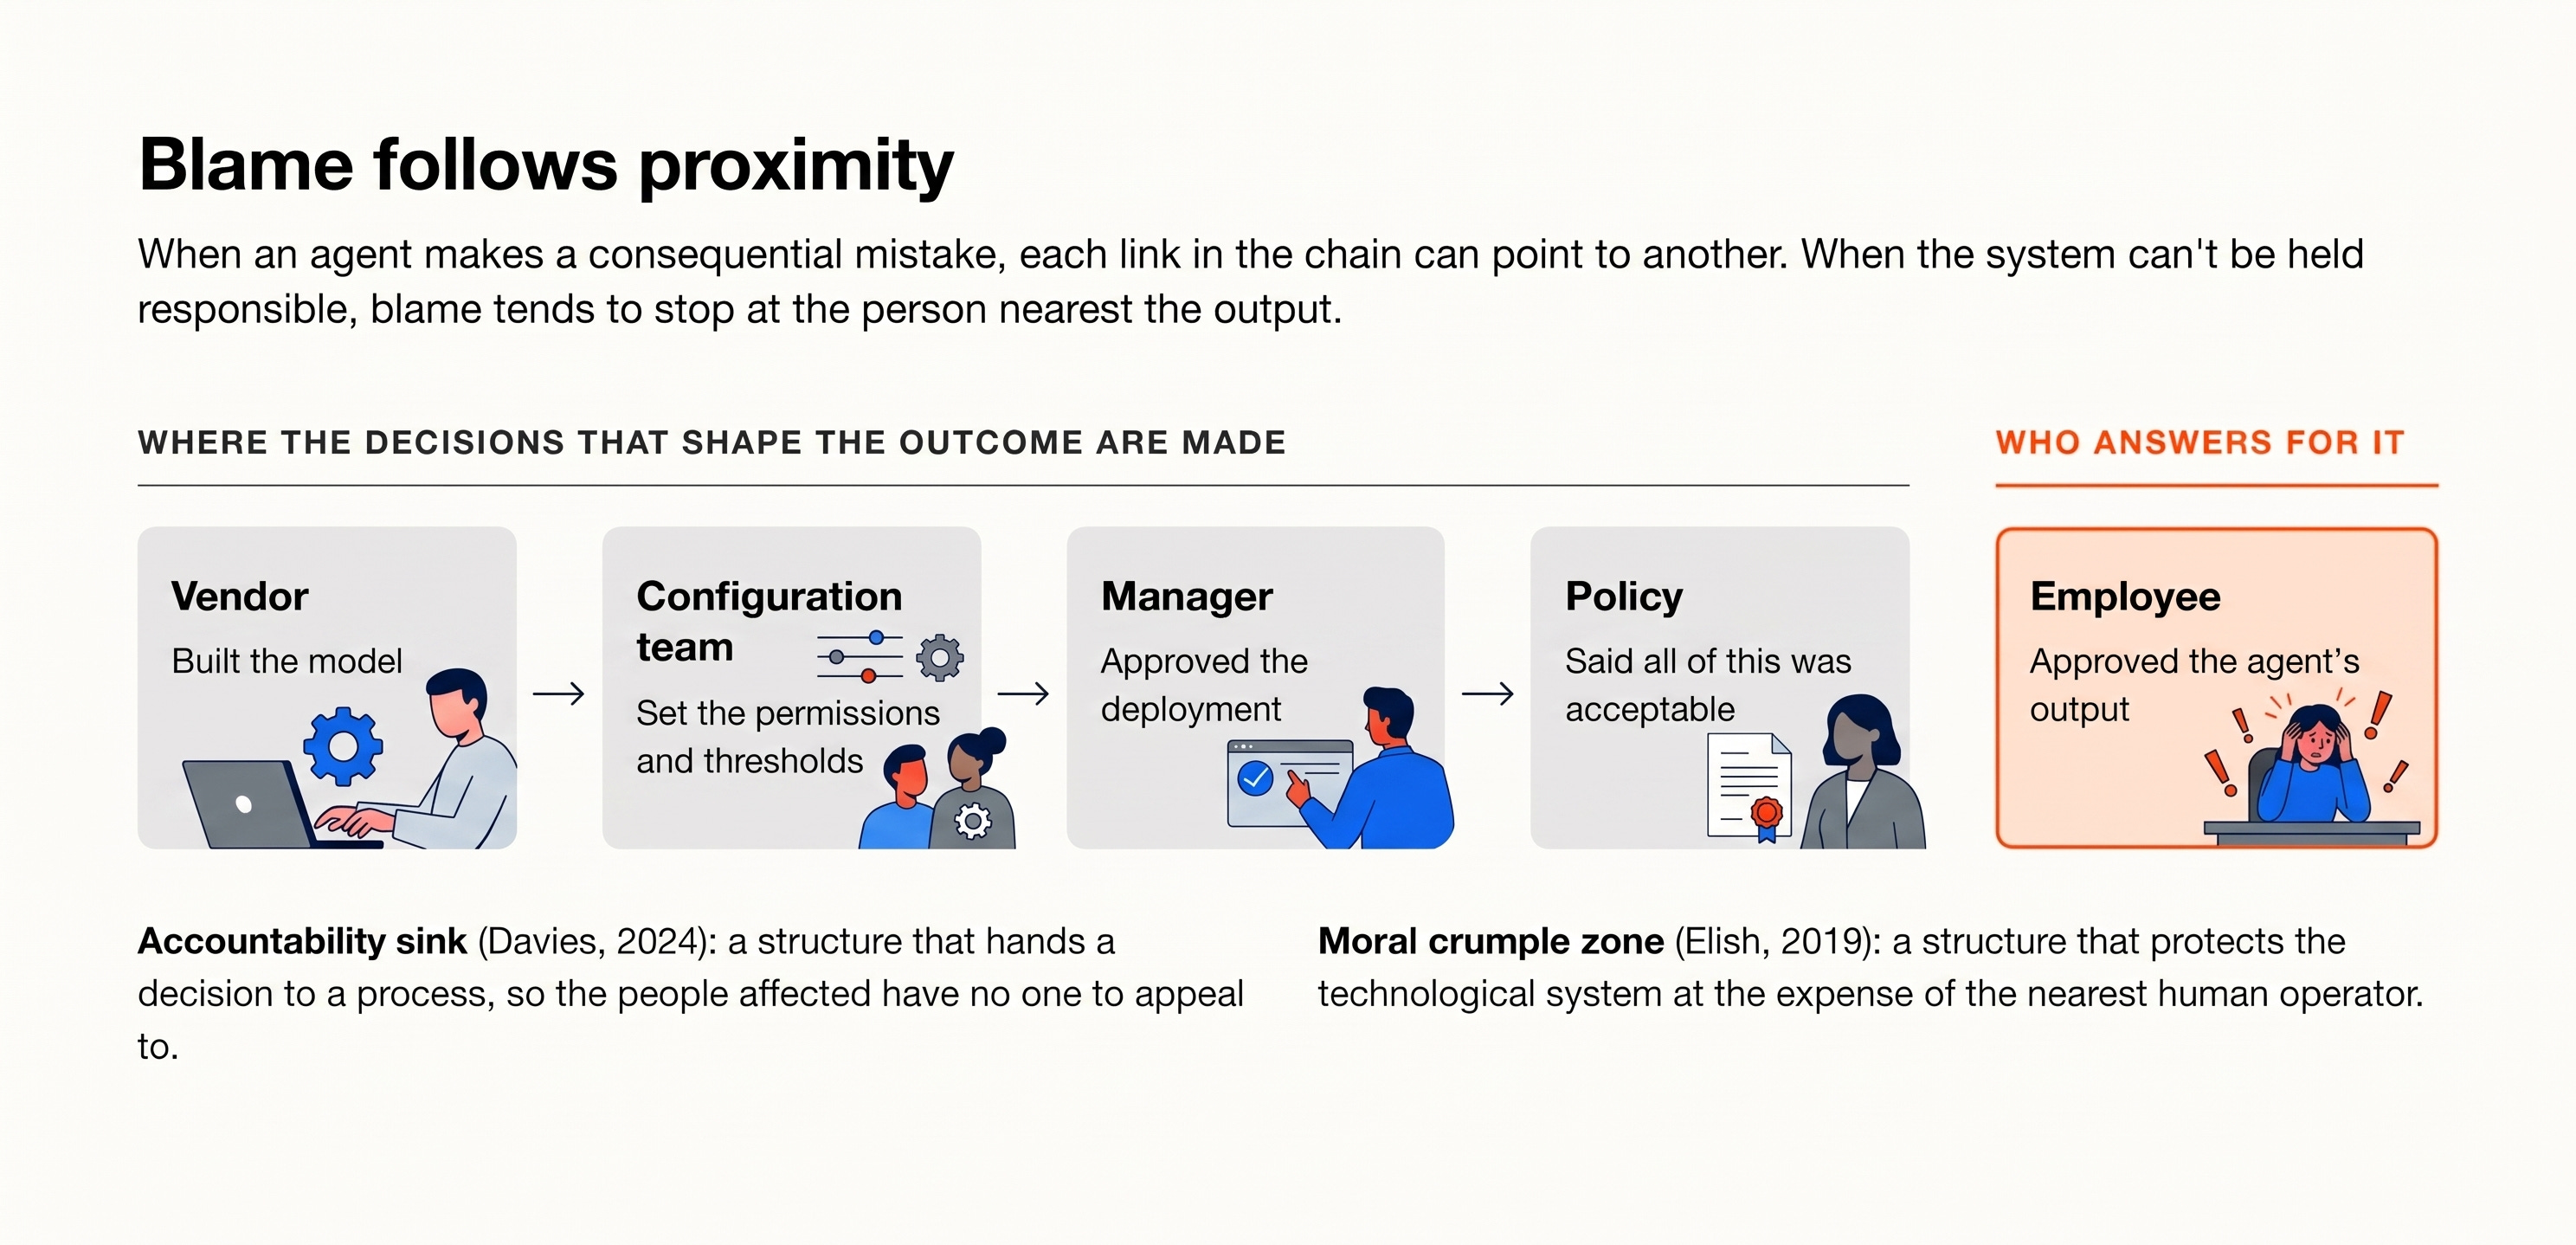
Proximity isn’t always unfair. The lawyers in Mata v. Avianca were sanctioned for filing cases ChatGPT invented. They were nearest the output, and they also had the authority and the professional duty to check it. The safety driver had far less say over how the system was designed and tested. The question is whether proximity came with authority. Adding central approval in the name of accountability often answers it badly. The people closest to the work stay answerable for outcomes, while the decisions that shape those outcomes are made somewhere else.
Robert Karasek’s 1979 demand–control model predicts the cost. Jobs that combine high demands with little decision latitude, meaning little say over how the work is done, are linked to mental strain. Answering for an agent’s output without authority over its configuration fits that description. I couldn’t find a study of strain among people who supervise AI agents, so this is an inference from older research. Karasek’s model also describes the alternative: high demands paired with high latitude make what the model calls active jobs, which Karasek predicted would build new skills and behavior.
Who keeps the agency
The title’s question has two answers, and the gap between them is the problem. On paper, the person nearest the output keeps the agency. Regulators expect that person to have authority, governance frameworks name them as the safeguard, and blame finds them when something breaks. In practice, more of the agency belongs to whoever set the thresholds, wrote the permissions, and decided which actions need a human at all.
Verna has a line that I think describes the leadership job in this setting. Once AI makes execution cheap, what matters most is “knowing what to do, when to interfere, what good looks like, and when something is actually done.” Verna calls Lovable “exactly one data point,” but the line names the same three tasks the human role narrows to: directing, stopping, and judging. It applies to people working with agents and to people working with each other.
So whatever structure an organization chooses, I’d test it against five questions. The first two are about directing, the third about when to step in or stop, and the last two about judging. Does each person know:
what matters most to the company right now
what they should be working on
when to step into someone else’s work, and when to stay out
what good looks like
when something is done to standard
If people can’t answer those, they can’t calibrate trust in an agent or in a colleague, and they’ll default to waiting for permission or to approving whatever the agent proposes. The fourth question may be the hardest. Lovable tests its work by asking whether it’s lovable. That’s a shared standard, and shared standards are something companies tend to underinvest in when speed is what gets rewarded.
The evidence for much of this is early. Most of it comes from chat assistants rather than agents that carry out multi-step work on their own, and much of the agent-specific data comes from companies studying their own products. One experiment I’d most like to see hasn’t been run. Caspar and colleagues found in 2016 that following orders measurably reduced people’s sense of agency over the outcomes of their own actions. I haven’t found a test of whether approving an AI’s proposed action does the same.
Milgram’s subjects could at least point to the experimenter in the lab coat. The person approving an agent’s work can point to a vendor, a configuration team, and a policy, and none of them will answer for the outcome. Whether that person ends up as Bandura’s principal or Milgram’s instrument gets decided before the agent makes its first proposal, by whoever sets the permissions, the thresholds, and the standard for good. Most organizations haven’t made those decisions on purpose yet.
References
Bainbridge, L. (1983). Ironies of automation. Automatica, 19(6), 775–779. https://doi.org/10.1016/0005-1098%2883%2990046-8
Bandura, A. (2001). Social cognitive theory: An agentic perspective. Annual Review of Psychology, 52, 1–26. https://doi.org/10.1146/annurev.psych.52.1.1
Bastani, H., Bastani, O., Sungu, A., Ge, H., Kabakcı, Ö., & Mariman, R. (2025). Generative AI without guardrails can harm learning: Evidence from high school mathematics. Proceedings of the National Academy of Sciences, 122(26), e2422633122. https://doi.org/10.1073/pnas.2422633122
Becker, J., Rush, N., Barnes, E., & Rein, D. (2025). Measuring the impact of early-2025 AI on experienced open-source developer productivity (arXiv:2507.09089). METR. https://doi.org/10.48550/arXiv.2507.09089
Brynjolfsson, E., Li, D., & Raymond, L. (2025). Generative AI at work. The Quarterly Journal of Economics, 140(2), 889–942. https://doi.org/10.1093/qje/qjae044
Budzyń, K., Romańczyk, M., Kitala, D., Kołodziej, P., Bugajski, M., Adami, H. O., Blom, J., Buszkiewicz, M., Halvorsen, N., Hassan, C., Romańczyk, T., Holme, Ø., Jarus, K., Fielding, S., Kunar, M., Pellise, M., Pilonis, N., Kamiński, M. F., Kalager, M., . . . Mori, Y. (2025). Endoscopist deskilling risk after exposure to artificial intelligence in colonoscopy: A multicentre, observational study. The Lancet Gastroenterology & Hepatology, 10(10), 896–903. https://doi.org/10.1016/S2468-1253%2825%2900133-5
Buçinca, Z., Malaya, M. B., & Gajos, K. Z. (2021). To trust or to think: Cognitive forcing functions can reduce overreliance on AI in AI-assisted decision-making. Proceedings of the ACM on Human-Computer Interaction, 5(CSCW1), Article 188. https://doi.org/10.1145/3449287
Caspar, E. A., Christensen, J. F., Cleeremans, A., & Haggard, P. (2016). Coercion changes the sense of agency in the human brain. Current Biology, 26(5), 585–592. https://doi.org/10.1016/j.cub.2015.12.067
Davies, D. (2024). The unaccountability machine: Why big systems make terrible decisions—and how the world lost its mind. Profile Books.
Elish, M. C. (2019). Moral crumple zones: Cautionary tales in human-robot interaction. Engaging Science, Technology, and Society, 5, 40–60. https://doi.org/10.17351/ests2019.260
Feng, K. J. K., McDonald, D. W., & Zhang, A. X. (2025, July 28). Levels of autonomy for AI agents. Knight First Amendment Institute at Columbia University. https://knightcolumbia.org/content/levels-of-autonomy-for-ai-agents-1
Green, B. (2022). The flaws of policies requiring human oversight of government algorithms. Computer Law & Security Review, 45, Article 105681. https://doi.org/10.1016/j.clsr.2022.105681
Karasek, R. A., Jr. (1979). Job demands, job decision latitude, and mental strain: Implications for job redesign. Administrative Science Quarterly, 24(2), 285–308. https://doi.org/10.2307/2392498
Kim, S. S. Y., Liao, Q. V., Vorvoreanu, M., Ballard, S., & Vaughan, J. W. (2024). “I’m not sure, but…”: Examining the impact of large language models’ uncertainty expression on user reliance and trust. In Proceedings of the 2024 ACM Conference on Fairness, Accountability, and Transparency (pp. 822–835). ACM. https://doi.org/10.1145/3630106.3658941
Lee, H.-P., Sarkar, A., Tankelevitch, L., Drosos, I., Rintel, S., Banks, R., & Wilson, N. (2025). The impact of generative AI on critical thinking: Self-reported reductions in cognitive effort and confidence effects from a survey of knowledge workers. In Proceedings of the 2025 CHI Conference on Human Factors in Computing Systems (Article 1121). ACM. https://doi.org/10.1145/3706598.3713778
Mata v. Avianca, Inc., 678 F. Supp. 3d 443 (S.D.N.Y. 2023).
Milgram, S. (1974). Obedience to authority: An experimental view. Harper & Row.
Noy, S., & Zhang, W. (2023). Experimental evidence on the productivity effects of generative artificial intelligence. Science, 381(6654), 187–192. https://doi.org/10.1126/science.adh2586
OECD. (2026). Agentic AI in organisations: Early insights from practitioner interviews (OECD Artificial Intelligence Papers, No. 65). OECD Publishing. https://doi.org/10.1787/1257a26f-en
Regulation (EU) 2024/1689 of the European Parliament and of the Council of 13 June 2024 laying down harmonised rules on artificial intelligence (Artificial Intelligence Act). (2024). Official Journal of the European Union, L, 2024/1689. https://eur-lex.europa.eu/eli/reg/2024/1689/oj
Regulation (EU) 2026/1744 of the European Parliament and of the Council of 8 July 2026 amending Regulations (EU) 2024/1689, (EU) 2018/1139 and (EU) 2023/1230 as regards the simplification of the implementation of harmonised rules on artificial intelligence (Digital Omnibus on AI). (2026). Official Journal of the European Union, L, 2026/1744. https://eur-lex.europa.eu/eli/reg/2026/1744/oj
Rubel, A., Castro, C., & Pham, A. (2019). Agency laundering and information technologies. Ethical Theory and Moral Practice, 22(4), 1017–1041. https://doi.org/10.1007/s10677-019-10030-w
Shavit, Y., Agarwal, S., Brundage, M., Adler, S., O’Keefe, C., Campbell, R., Lee, T., Mishkin, P., Eloundou, T., Hickey, A., Slama, K., Ahmad, L., McMillan, P., Beutel, A., Passos, A., & Robinson, D. G. (2023). Practices for governing agentic AI systems. OpenAI. https://cdn.openai.com/papers/practices-for-governing-agentic-ai-systems.pdf
Shen, J. H., & Tamkin, A. (2026). How AI impacts skill formation (arXiv:2601.20245). arXiv. https://doi.org/10.48550/arXiv.2601.20245
Vaccaro, M., Almaatouq, A., & Malone, T. (2024). When combinations of humans and AI are useful: A systematic review and meta-analysis. Nature Human Behaviour, 8(12), 2293–2303. https://doi.org/10.1038/s41562-024-02024-1
Vasconcelos, H., Jörke, M., Grunde-McLaughlin, M., Gerstenberg, T., Bernstein, M. S., & Krishna, R. (2023). Explanations can reduce overreliance on AI systems during decision-making. Proceedings of the ACM on Human-Computer Interaction, 7(CSCW1), Article 129. https://doi.org/10.1145/3579605
Verna, E. (2026, September 24). What it’s like to work at an AI-native company. Elena Verna [Substack]. https://www.elenaverna.com/p/what-its-like-to-work-at-an-ai-native
Very helpful... thank you! This concept of 'agency laundering' (thank you - new term for me) is already in play. A couple of my clients have ER cases where AI produced consequential analysis. It was wrong and unchecked, and things went downhill fast. The associated humans are blaming AI for the ensuing issues. "It was the AI, not me!!" This is very common in human-only environments (sadly), but, as your article notes, the zone of control and associated accountability were easier to see when only humans were involved.
Weird and wild world, isn't it!
Thanks, Shonna...
"The cue that matters most, though, is a standard." This is the line I keep coming back to. In code review I have started asking one plain question of AI-generated changes: would you be happy to maintain this? It helps because the reviewer holds the output against something, instead of a feeling that it looks fine. Your METR example shows how unreliable that feeling can be. In my view each department needs its own version of that question, written down and owned by someone close to the work, otherwise approval slowly becomes a habit rather than a judgement. You say the fourth question may be the hardest. When a team does manage to write its standard down, who usually ends up owning it: the manager, the reviewers, or the people doing the work?